Case Study · AI Deployment
Trustdesk
Fills in security questionnaires from a company's own documentation. Every answer shows where it comes from, and when the documentation doesn't say, neither does the tool.
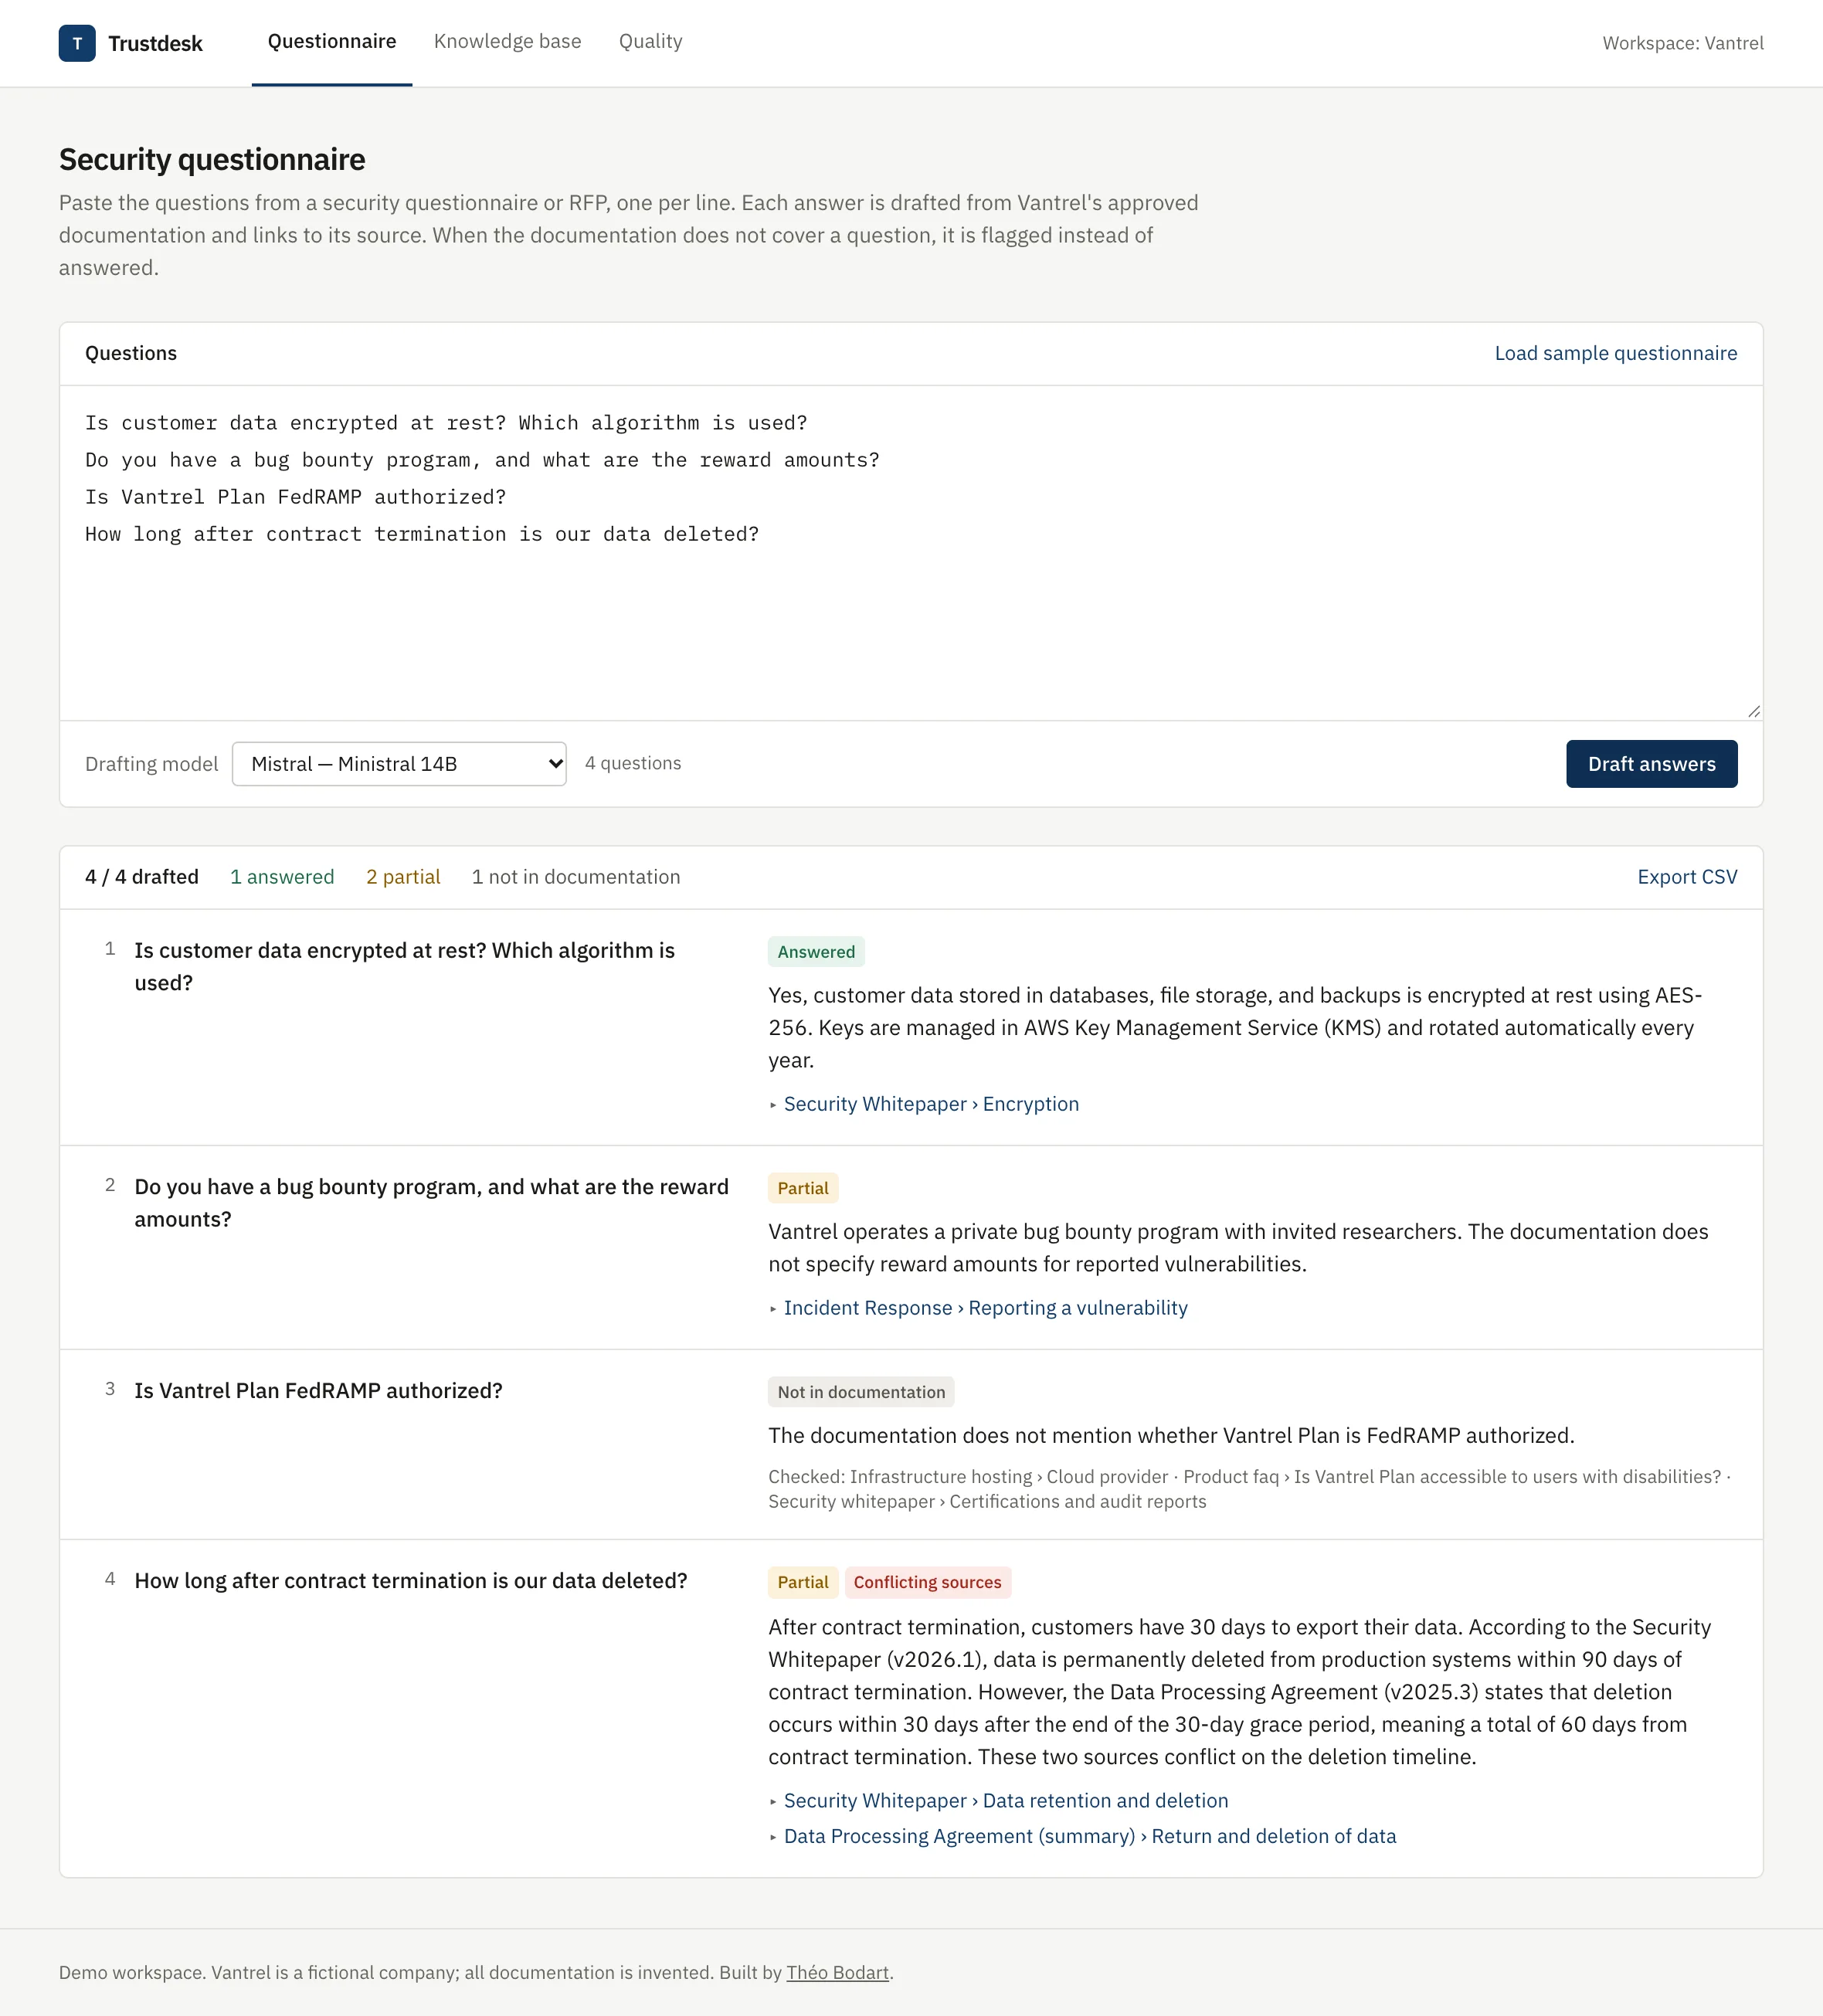
Four questions, four outcomes. Each answer links to the section it was taken from.
The problem
Software vendors selling to large companies get the same spreadsheet over and over: a few hundred questions on encryption, hosting, certifications, backups. Someone spends days copying answers out of a security whitepaper and a data processing agreement.
Writing the text is the easy part to automate. The catch is that these answers end up in contracts, so a confident wrong "yes" is worse than an empty cell. Trustdesk is built around that: four possible outcomes, and never an answer without a source.
The documentation answers it, including a documented "no".
Part of it is documented. The answer says which part isn't.
Nothing to cite, so nothing claimed. It shows what was checked.
Two documents disagree. Both are quoted, nobody picks one silently.
The documentation belongs to Vantrel, a software company I invented: twelve documents, written with the gaps, near-misses and one contradiction that real documentation always has.
How an answer is produced
1 · Search
Find the 5 closest sections
By meaning, not keywords, so a French question still finds an English page.
2 · Draft
The model reads only those
It returns a status, the answer, and which sections it used.
3 · Check
Code verifies the sources
A source that wasn't provided is removed. No valid source, no answer.
4 · Review
A person sends it
The tool drafts. Anything uncertain is flagged, not hidden.
How I know it works
Every change runs against the same 50 questions, each with a reference answer. Some are easy. Others are traps: rephrased questions, questions in French, answers spread across three documents, and twelve questions the documentation simply doesn't answer. One model drafts, the other grades, and plain code counts the answers that claim something the documentation doesn't say.
Invented answers on the 12 undocumented questions, by prompt version
Version 3 got the best grade of the three. Version 2 is the one in use, because it's the only one where neither model made anything up. Its cost: out of the 38 questions the documentation does answer, 2 were marked "not documented" with Mistral and 1 with Gemini. Those go to a person, with the sections that were checked. I picked the version whose mistakes are cheap, not the one with the highest score.
What the numbers changed
Each of these went against what I expected before measuring.
The textbook search lost
Share of the right sections found in the top 5 results. Mixing keyword and meaning search is the usual advice, but here meaning alone did better: keywords pushed the wrong sections up on rephrased questions.
I checked the graders against a person
I graded 13 answers by hand. Gemini agreed with me on 12, Ministral 14B on 2: it rejected correct answers. Its scores measured its own strictness, so Gemini now does the grading.
Free tiers decide the design
Two Mistral models I planned on had a quota of zero, and Gemini allows 500 calls a day. Every run records which model actually answered, not the one requested.
Why I build these
I'm a functional consultant moving into Solutions Engineering. Deploying a model is mostly deciding what "good" means for the people who will rely on it, then checking with numbers that you got there.